Models and infrastructure
Model selection, inference economics, local deployment, compression and serving architecture.
- Blog posts
- 57
- Topic
- AI and agents
Start with the cornerstone
Get the next AI and agents field note
One concise email when we publish. No tracking pixels, and no inbox filler.
Latest in this collection
 AI & Agents
Laya vs Jev: What the Benchmarks Mean for AI Startups
Can an open specialist undermine a two-year head start? What Laya actually shows, what the Jev comparison misses, and where a defensible AI business can create value.
 AI & Agents
Jev AI Review: Decision Models for Agent Workflows
Jev makes typed decisions instead of prose. See how it can route models, govern agent control steps and support bounded automation without replacing hard rules.
 AI & Agents
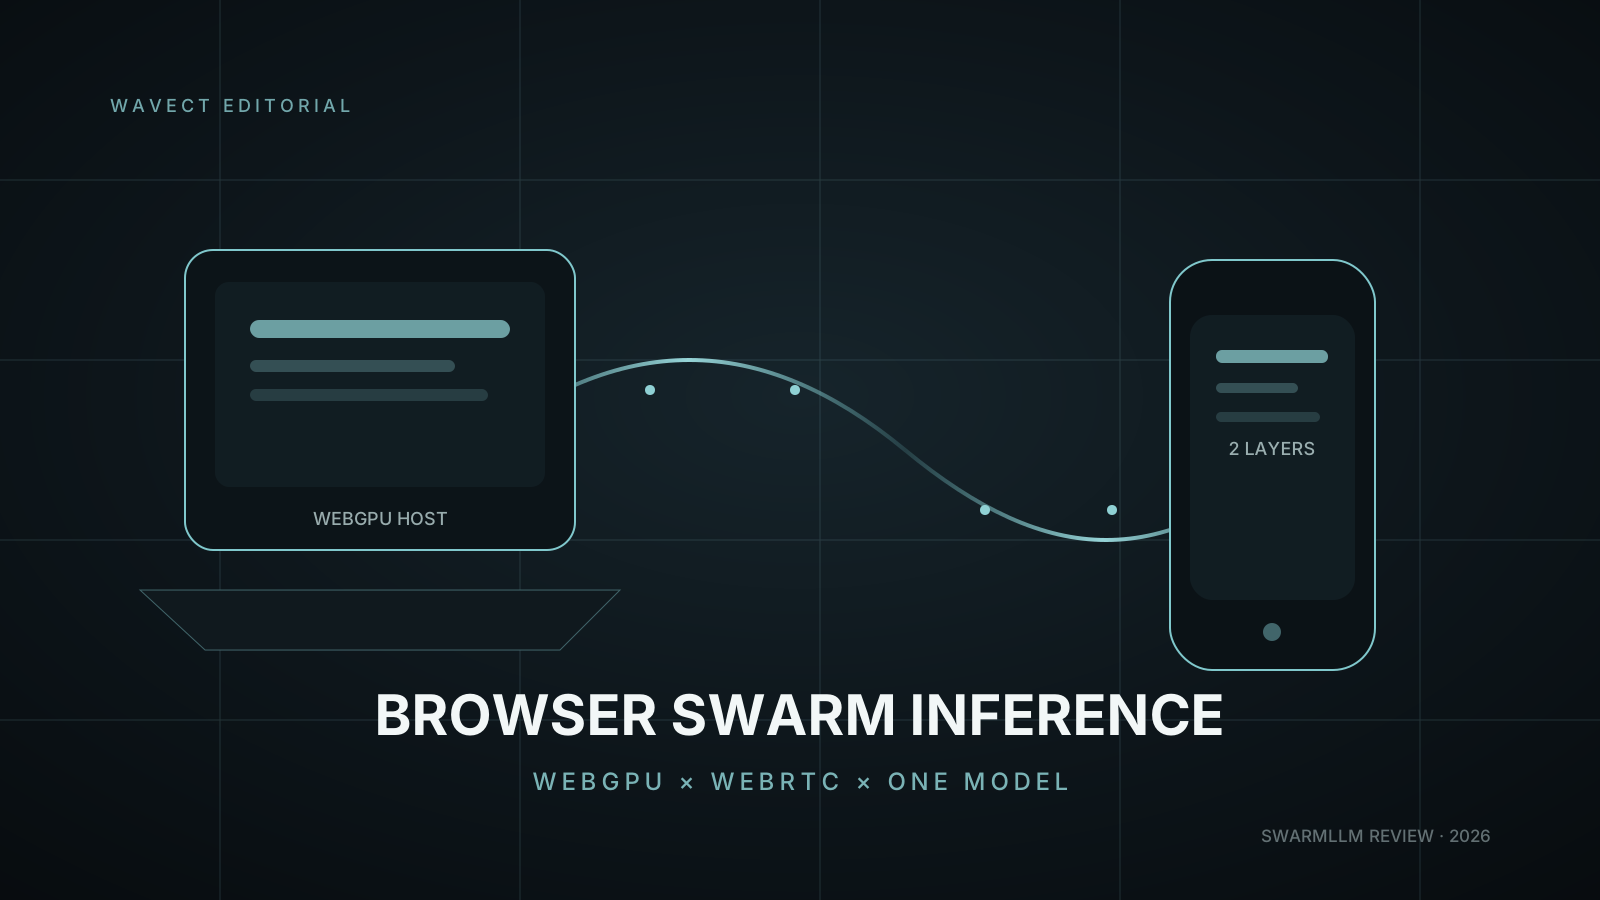
SwarmLLM Review 2026: Browser P2P LLM Inference Across Phones and Laptops
A buyer-focused review of SwarmLLM: browser-native 27B inference across phones and laptops, WebGPU/WebRTC architecture, benchmark limits, peer trust, and when to pilot it.
 AI & Agents
Phonely Alma Review: Is the Voice LLM Ready for Production?
Alma claims 182 ms TTFT, a 206 ms P99 and $0.55 per blended million tokens. See what the benchmark proves, what it omits and how to run a buyer-side voice-agent pilot.
 AI & Agents
Utopia Review: Temporal Knowledge Graph for Enterprise
Evaluate Utopia for enterprise knowledge: two-clock history, source provenance, self-hosting limits and a practical pilot plan before you invest.
 AI & Agents
NVIDIA PAIR Review: Local AI Routing and the AMD Gap
PAIR routes independent agent requests across local computers without pooling GPUs. See how it works, where Strix Halo falls short and what an AMD port must prove.
Complete article directory
- Laya vs Jev: What the Benchmarks Mean for AI Startups
- Jev AI Review: Decision Models for Agent Workflows
- SwarmLLM Review 2026: Browser P2P LLM Inference Across Phones and Laptops
- Phonely Alma Review: Is the Voice LLM Ready for Production?
- Utopia Review: Temporal Knowledge Graph for Enterprise
- NVIDIA PAIR Review: Local AI Routing and the AMD Gap
- Tencent Hy4 Preview Review: Is the 1M-Context Coding Model Worth a Pilot?
- PageLM Review: Self-Hosting and Commercial Use
- M6 Mac mini vs M5 Mac Studio for Local AI: Buyer's Guide
- FreeToken AI Review: Run Frontier MoE Models on Consumer GPUs?
- Darkbloom AI Review: Private Inference on Idle Macs
- Ox Alpha Revealed as GLM-5.3-Flash: What Changed
- Pika Audio Models API Pricing: Is SFX Really 20x Cheaper?
- Thunder Compute's $13M GPU Virtualization Bet: Enterprise Buyer's Guide
- AirLLM on 4 GB VRAM: How Layer-Wise Inference Really Works
- Qwen3.8-27B: Self-Hosted Computer-Use Agents Without Exporting Screenshots
- Netflix's vLLM and Triton Stack: 7 Production Lessons
- Transformers.js Browser AI: When Local Inference Belongs in Your Product
- How to Self-Host LiteLLM in Production: 2026 Guide
- AI-Ready Company Wiki: Architecture and Build Guide
- Does Claude Watermark Text? The 2026 API Answer
- OpenKB Review: Knowledge Compiler vs RAG
- Unsloth Desktop Review: A Private Local AI Workstation?
- NeMo Switchyard 0.2: Agent Model Routing Without Training?
- Firecrawl AnyDoc Review: 14 Formats to Markdown
- Muse Glimmer 30B: Is Meta's Local Agent Model Production-Ready?
- OmniRoute AI Routing: Setup and Production Checklist
- Gemini Robotics 2: Whole-Body Control and the Pilot Decision
- pdf-inspector Review: Route PDFs Before OCR
- Local Multimodal AI Coding Assistant: Voice, OCR and Privacy
- DeepSeek V4 Flash 0731 on One AI PC: What Actually Works?
- Fine-Tune Gemma 4 Free with Unsloth and Colab
- Taalas HC1 Review: Is a Hardwired LLM ASIC Worth It?
- llmfit Guide: Which Local LLM Fits Your Hardware?
- Miso TTS Self-Hosted vs API: Cost, Latency and VRAM Reality
- Compress RAG Vectors to 2 Bits: Is Data-Oblivious Quantization Production-Ready?
- LMCache Reported 13.7x Lower Mean TTFT with a Shared KV Cache
- Lossless LLM Weight Compression vs 8-bit GGUF: What Is Ready for Production?
- Cisco Antares Review: 1B Local AI for Vulnerability Localization
- NVIDIA Nemotron 3.5 ASR: Is Free Self-Hosted STT Ready for Voice Agents?
- Kimi K3 for EU Companies: API Cost, Data Risk, and a Pilot Plan
- Mesh LLM Review: Can One Large LLM Run Across Multiple Computers?
- Bonsai 27B Review: Can a 27B LLM Really Run on a Phone?
- Soofi S: Is Germany's Sovereign LLM Ready for Business?
- Colibri Runs GLM-5.2 on Consumer Hardware. Here Is the Catch.
- When Local Models Beat APIs: A Break-Even Calculator for EU Companies
- LLM Cost Calculator 2026: Cost per Task, Not Cost per Token
- Pxpipe Review: Can Images Cut Claude Code Token Costs 60%?
- Cheaper Per Token Can Still Cost More Per Task
- Anthropic Says No Open-Weights Ban. The Cost War Is Still Real.
- LLM Gateways Compared 2026: LiteLLM vs OpenRouter vs Portkey vs RouteLLM
- Self-Hosting LLMs in the EU: When Open Weights Actually Pay Off
- Best Open-Weight LLMs 2026: DeepSeek vs Qwen vs Kimi vs GLM vs Llama
- How to Cut LLM Token Costs in 2026
- When Is an LLM Eval Worth Building? Cost, ROI, and Trusting the Judge
- RAG vs Fine-Tuning vs Long-Context 2026
- LLM API Costs 2026. Architecture Shift